Gemini 4 Carbon hasn’t just topped the Artificial Analysis Intelligence Index — it’s putting up a strong showing on all benchmarks.
Following its top-tier rankings on static benchmarks, Google DeepMind’s latest flagship model, Gemini 4 Carbon (High), has posted dominant results on crowdsourced, human-evaluated platform Arena.AI. Across thousands of blind side-by-side preference battles, Gemini 4 Carbon took the #1 spot on the Text Arena while capturing 2nd place on the Agent Arena, solidifying its position as one of the most capable models available.
Dominating the Text Arena
In the main Text Arena leaderboard, Gemini 4 Carbon (High) claimed first place overall with an Arena Elo score of 1,528. It surpassed Google’s sibling model, Gemini 4 Argon (High), which sat in second place with a score of 1,520.
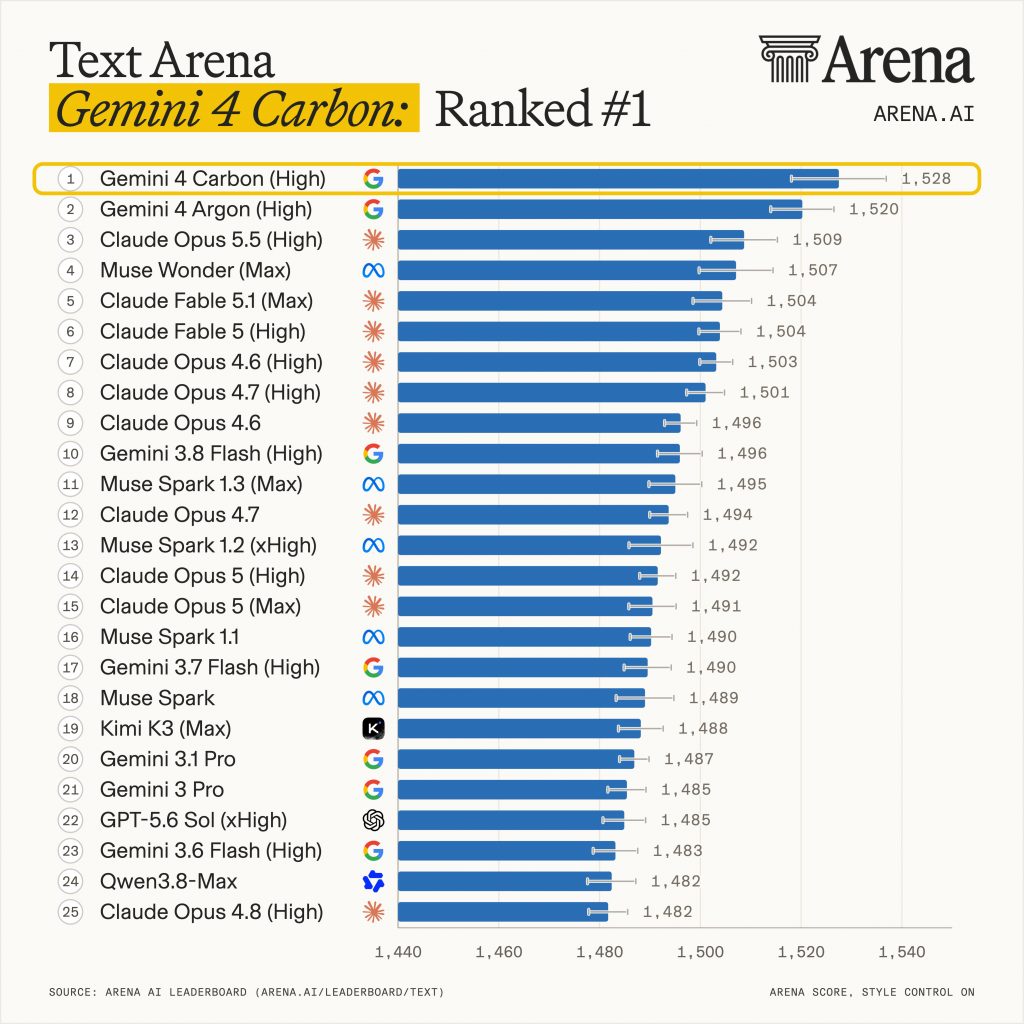
The victory places Gemini 4 Carbon ahead of prominent flagship competitors. Anthropic’s Claude Opus 5.5 (High) ranked third with a score of 1,509, followed by Meta’s Muse Wonder (Max) at 1,507 and Anthropic’s Claude Fable 5.1 (Max) at 1,504. The Text Arena evaluates core large language model capabilities across open-ended conversation, creative writing, instruction following, and reasoning, showing a distinct preference among human voters for Carbon’s tone, accuracy, and response structure.
Strong Agentic and Web Development Capabilities
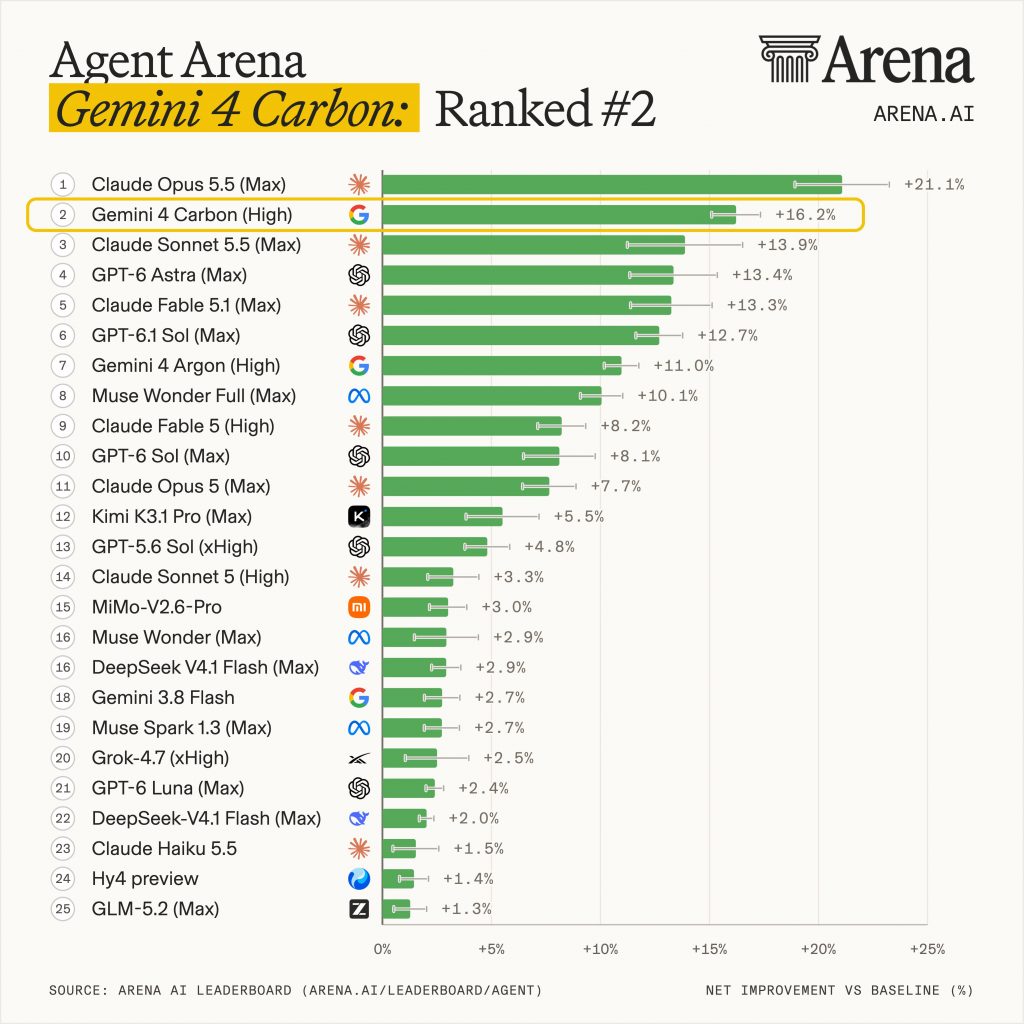
On the Agent Arena—which measures net improvement over baseline models in executing multi-step autonomous workflows and computer-use tasks—Gemini 4 Carbon (High) secured the #2 spot globally. It achieved a +16.2% net improvement over baseline, finishing second only to Anthropic’s Claude Opus 5.5 (Max), which led the board with +21.1%. Carbon outperformed rivals like Claude Sonnet 5.5 (+13.9%) and OpenAI’s GPT-6 Astra (+13.4%).
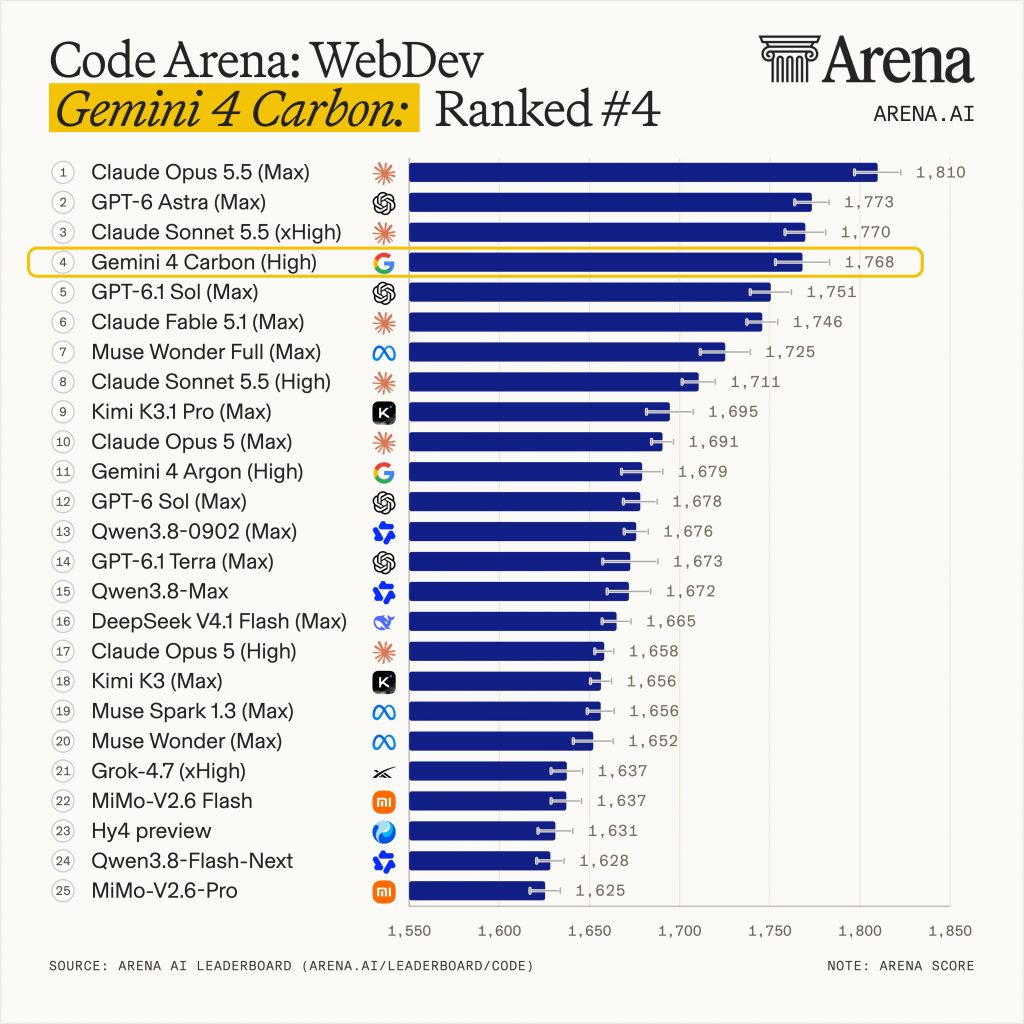
Google’s new model also put up a strong showing in web development. On the Code Arena: WebDev leaderboard, Gemini 4 Carbon (High) ranked #4 overall with an Arena score of 1,768. It trailed closely behind Claude Opus 5.5 (1,810), GPT-6 Astra (1,773), and Claude Sonnet 5.5 (1,770).
Google’s Frontier Shift
Historically, Google models struggled to beat Anthropic and OpenAI on crowdsourced coding and agent leaderboards. However, Gemini 4 Carbon’s top placements across Arena signal a major technical turnaround. By leading in general text interaction and holding elite rankings in agentic execution, Google DeepMind appears to have delivered a balanced, multi-domain contender in Gemini 4 Carbon capable of handling both conversational logic and complex enterprise automation.