Google has launched Gemini 4 Neon, the newest model in its Gemini 4 family, and the benchmark table it released has the model ahead of Claude Opus 5.5 and GPT-6.2 Sol on most of the evaluations it lists. Neon leads on 16 of the 19 results in the comparison, including the Artificial Analysis Intelligence Index, where it scores 61 against 59 for Opus 5.5 and 57 for GPT-6.2 Sol.
Neon is pitched as the model that brings close-to-Carbon intelligence at Flash-tier speed and cost. Google describes it as a frontier model for complex software engineering, knowledge work and science workflows, and it’s the fourth new Gemini model the company has shipped in about a month, following Carbon, Argon and Hydrogen.
What Gemini 4 Neon is
Neon builds on Gemini 4 Hydrogen with deeper reasoning, according to its Vertex AI model page, and is positioned for coding, reasoning and production agents. It takes text, images, video, audio and PDFs as input, with a context window of about one million tokens.
Pricing is $3 per million input tokens and $15 per million output tokens, the same figures that showed up in Google Cloud’s SKU listing ahead of launch. That makes it pricier than Hydrogen ($1.50/$7.50) and above the introductory $2/$10 rate for Carbon and Argon, which doubles to $4/$20 on December 1.
Neon is rolling out in the Gemini API in Google AI Studio, to Gemini for business, in Google Antigravity for paid Pro and Ultra subscribers, and in the Gemini app for Pro and Ultra subscribers, where it replaces Gemini 3.1 Pro.
Gemini 4 Neon benchmarks
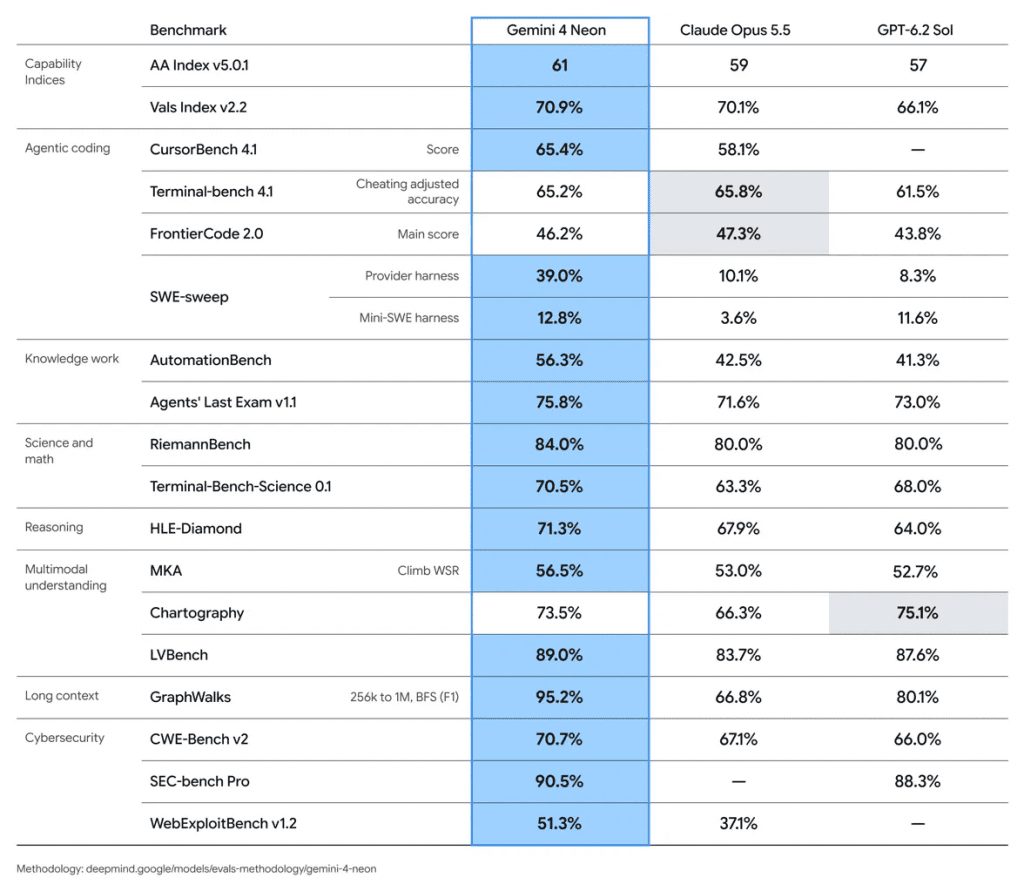
The table Google published compares Neon with Claude Opus 5.5 and GPT-6.2 Sol across capability indices, coding, knowledge work, science, reasoning, multimodal, long context and cybersecurity.
Capability indices. Gemini 4 Neon scores 61 on the Artificial Analysis Intelligence Index v5.0.1, ahead of Opus 5.5 at 59 and GPT-6.2 Sol at 57. On the Vals Index v2.2 it posts 70.9%, a narrow lead over Opus 5.5’s 70.1%, with GPT-6.2 Sol at 66.1%.
Agentic coding. The picture here is mixed. Gemini 4 Neon leads on CursorBench 4.1 with 65.4% against 58.1% for Opus 5.5 (no score is listed for Sol), and the gap on SWE-sweep is large: 39.0% on the provider harness against 10.1% for Opus 5.5 and 8.3% for Sol, and 12.8% on the mini-SWE harness against 3.6% and 11.6%. But Opus 5.5 edges it on Terminal-bench 4.1 (cheating-adjusted accuracy), 65.8% to 65.2%, and on FrontierCode 2.0, 47.3% to 46.2%. Sol trails on both, at 61.5% and 43.8%.
Knowledge work. Neon scores 56.3% on AutomationBench, well clear of Opus 5.5 at 42.5% and Sol at 41.3%, and 75.8% on Agents’ Last Exam v1.1, ahead of Sol’s 73.0% and Opus 5.5’s 71.6%.
Science, math and reasoning. On RiemannBench Gemini 4 Neon gets 84.0%, against 80.0% for both rivals. It scores 70.5% on Terminal-Bench-Science 0.1 (Sol 68.0%, Opus 5.5 63.3%), and 71.3% on HLE-Diamond, against Opus 5.5’s 67.9% and Sol’s 64.0%.
Multimodal. Gemini 4 Neon leads on MKA (56.5%) and LVBench (89.0%, with Sol at 87.6% and Opus 5.5 at 83.7%). It loses to Sol on Chartography, 73.5% to 75.1%, though it’s well ahead of Opus 5.5’s 66.3%.
Long context. This is Gemini 4 Neon’s biggest margin. On GraphWalks, which tests breadth-first search from 256k to 1M tokens, it scores 95.2% against 80.1% for Sol and 66.8% for Opus 5.5.
Cybersecurity. Gemini 4 Neon scores 70.7% on CWE-Bench v2 (Opus 5.5 67.1%, Sol 66.0%), 90.5% on SEC-bench Pro against Sol’s 88.3% (no Opus score listed), and 51.3% on WebExploitBench v1.2 against Opus 5.5’s 37.1% (no Sol score listed). For reference, Google’s launch numbers for Gemini 4 Carbon were 88.2% on SEC-bench Pro and 71.0% on CWE-bench, so Neon edges its bigger sibling on the former and is just behind on the latter.
In all, Gemini 4 Neon doesn’t lead on three results: Terminal-bench 4.1 and FrontierCode 2.0, where Opus 5.5 is ahead, and Chartography, where Sol wins.
Not the top of the leaderboard
The comparison is against Opus 5.5 and GPT-6.2 Sol, not the most capable models from Anthropic and OpenAI. Per Artificial Analysis, Claude Fable 5.2 scores 65 on the index and GPT-6.2 Astra scores 62, both above Neon’s 61, while Gemini 4 Carbon is at 60. The Neon numbers are also Google’s own, and independent evaluations of the model are yet to land.
Even so, the result continues Google’s turnaround at the frontier. Only a few months ago, Gemini 3.5 Flash scored 50 on the index and Google dropped out of the top five labs for the first time. Gemini 4 Argon put it back near the frontier, and Carbon took the top spot on the index with a 59 before Fable 5.2 overtook it. Neon now scores a point above Carbon, and Google says it delivers that at Flash-tier speed and at a price below Carbon’s standard $4/$20 rate from December 1, making it the Gemini 4 model Google is positioning for everyday work.