Google sure seems to be on a tear with its new model releases.
Google’s newest model, Gemini 4 Neon, has edged past its own flagship on the Artificial Analysis Intelligence Index. Neon (xhigh) scores 61 on the index, one point ahead of Gemini 4 Carbon (high) at 60, which makes it the highest-scoring Google model the firm has measured. It places third overall, behind GPT-6.2 Astra (max) at 62 and Claude Fable 5.2 (max) at 65.
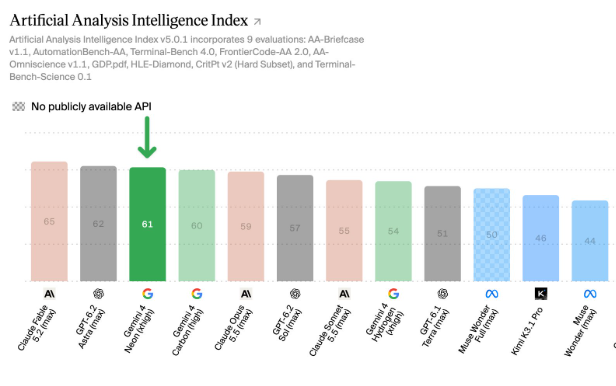
Neon is Google DeepMind’s fourth model in about seven weeks, following Argon, Carbon and Hydrogen. The headline gain is modest, but Artificial Analysis says it comes at a lower cost and in less time than Carbon.
A small intelligence gain at a lower cost
Neon (xhigh) costs $6.44 to run the Intelligence Index, about 17% less than Carbon’s $7.76 at its standard, non-discounted pricing. Artificial Analysis says Neon uses about 15% more output tokens per task, so the saving comes entirely from price: Neon costs $3 per million input tokens and $15 per million output tokens, 25% below Carbon’s standard $4/$20.
Against Carbon’s currently discounted rate of $2/$10, which runs out on November 30, Neon is actually 50% more expensive per token, as the pricing that surfaced before launch suggested.
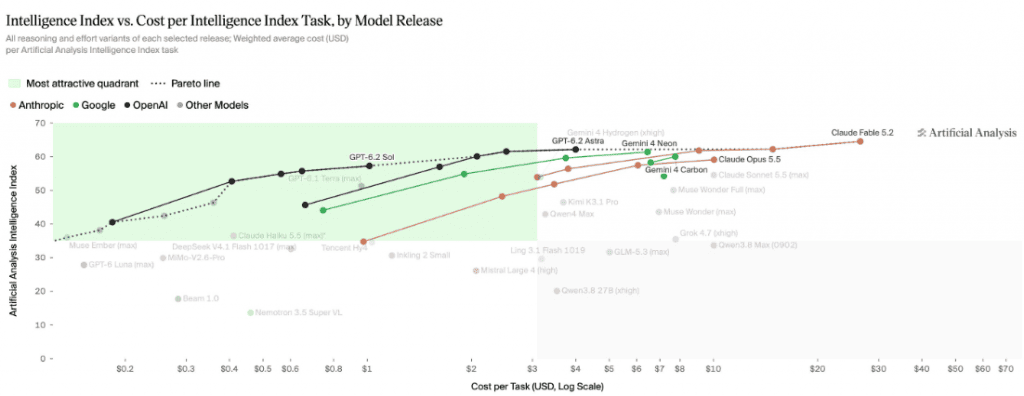
At high effort, Neon matches Carbon’s score of 60 for $3.74 per task, less than half of what Carbon costs. It’s also faster: Artificial Analysis measures Neon’s output speed at about 110 tokens per second, against about 57 for Carbon, and says that cuts the time per task by roughly 40.
OpenAI still holds the cost advantage at the top. GPT-6.2 Astra (max) completes the index for $4.00 per task, so Neon (xhigh) costs about 1.6 times as much for a score one point lower, and Claude Opus 5.5 (max) scores 59 at roughly $10 per task. Fable 5.2, the leader, costs far more at about $26.50.
Competitive with Claude on coding agents
Run with Google’s Antigravity CLI, Neon (xhigh) scores 59 on the Artificial Analysis Coding Agent Index, three points ahead of Carbon (high) at 55. That edges Claude Code with Claude Fable 5.2 (xhigh) and Claude Opus 5.5 (max), which both score 58, and sits well above Codex with GPT-6.2 Astra at 53 and GPT-6.2 Sol at 50.
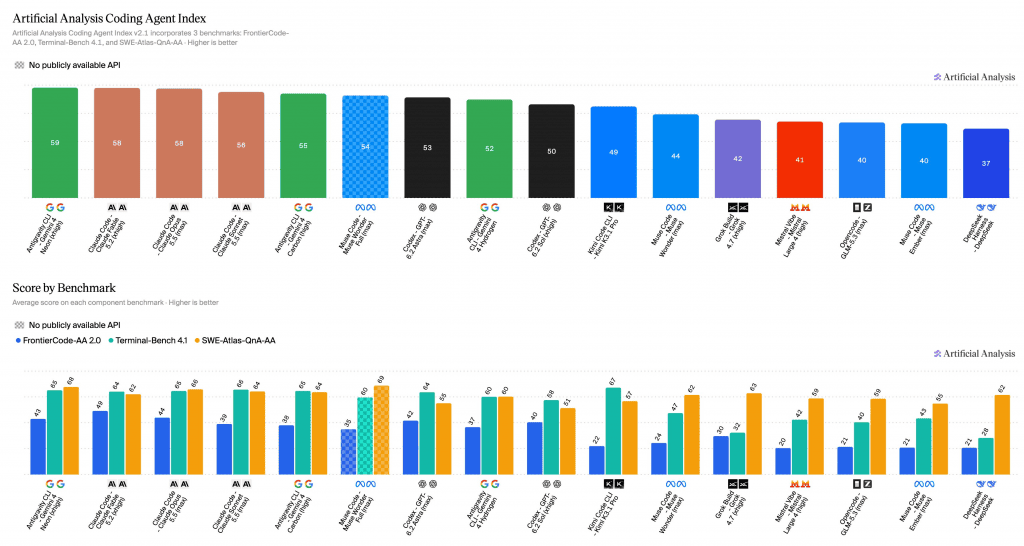
Neon’s scores on the index’s three components are 43 on FrontierCode-AA 2.0, 65 on Terminal-Bench 4.1 and 68 on SWE-Atlas-QnA-AA. Carbon scored 38, 65 and 64 respectively.
The cost gap is wide. An average task with Neon in Antigravity costs $6.86, against $12.61 for Claude Opus 5.5 (max) and $15.47 for Claude Fable 5.2 (xhigh). Coding is an area where Google has been catching up: Argon first placed third on this index behind only Claude Code, and Carbon with Antigravity scored 59, three points behind Opus 5.5.
Gains in visual reasoning and presentation
Artificial Analysis says Neon makes its biggest improvements in agentic knowledge work and visual reasoning:
- GDP.pdf: Neon (high) scores 33.4%, five points above Carbon (high) at 28.4% and in line with the highest scores measured. Neon (xhigh) scores 28.0%.
- AA-Briefcase: Neon (xhigh) scores 1700 Elo, 89 points above Carbon’s 1611, though still behind Claude Fable 5.2 (1785) and Claude Sonnet 5.5 (1815). The biggest jump is in Presentation Quality, up 170 Elo to 1771, the highest Artificial Analysis has measured and 45 points above the previous leader, Claude Sonnet 5.5 (1726).
- MKA: On Google’s Multimodal Knowledge Agent evaluation, Neon reaches a Climb WSR of 56%, up two points from Carbon and a point behind Fable 5.2 (57%).
Model details
Neon has a 1-million-token context window and takes text, image, video and speech input, with text output. It offers four effort levels (low, medium, high and xhigh), with xhigh first introduced to Gemini models with Hydrogen, which scored 54 on the index at that setting. Cached input tokens get the same 95% discount ($0.15) as other Gemini 4 models.
The model is available through Google’s API at launch, and Pro and Ultra subscribers can use it in Antigravity and the Gemini app. Google had described it as a fast reasoning model that brings quality close to Carbon at Flash-tier speed.
Back near the top
The result caps a strong turnaround for Google on the index. Not long ago it was out of the top five labs for the first time, and Carbon then took the top spot before Fable 5.2 overtook it. Google’s own launch table, in which Neon beats Opus 5.5 and GPT-6.2 Sol on most benchmarks, now has independent numbers backing it up, with Neon sitting a point above Carbon and two points above Opus 5.5.